Create an Iceberg sink connector
Use an Iceberg sink connector to keep Iceberg tables in S3 storage in step with your source tables. When Database Type names the source database, the connector applies the inserts, updates, and deletes from the Kafka topics you choose, while an Iceberg (logs) sink connector appends every record.
Prerequisites
- A CDC Service whose status is Healthy. See Create a CDC Service.
- Topics with change data, written by a source connector such as a PostgreSQL source connector.
- The URL and name of your Iceberg catalog, and the endpoint, access key, and secret of the S3 storage that holds the tables.
Create the connector
-
Select Data platform → Workspace management, then select your workspace.
-
On the Overview tab, under Services, select the CDC card.
-
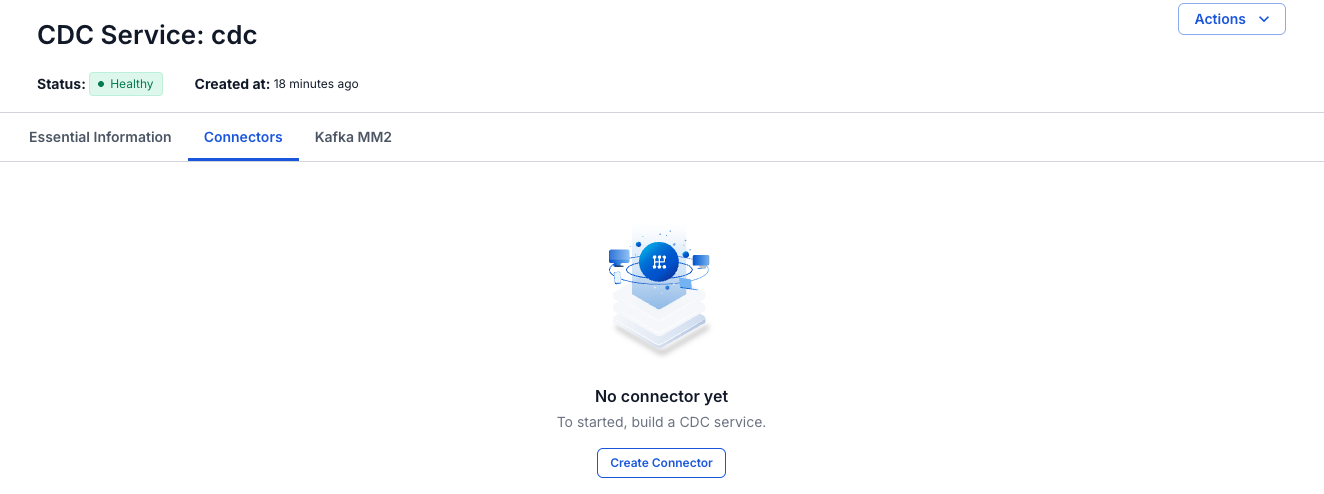
Select the Connectors tab, then select Create Connector.
-
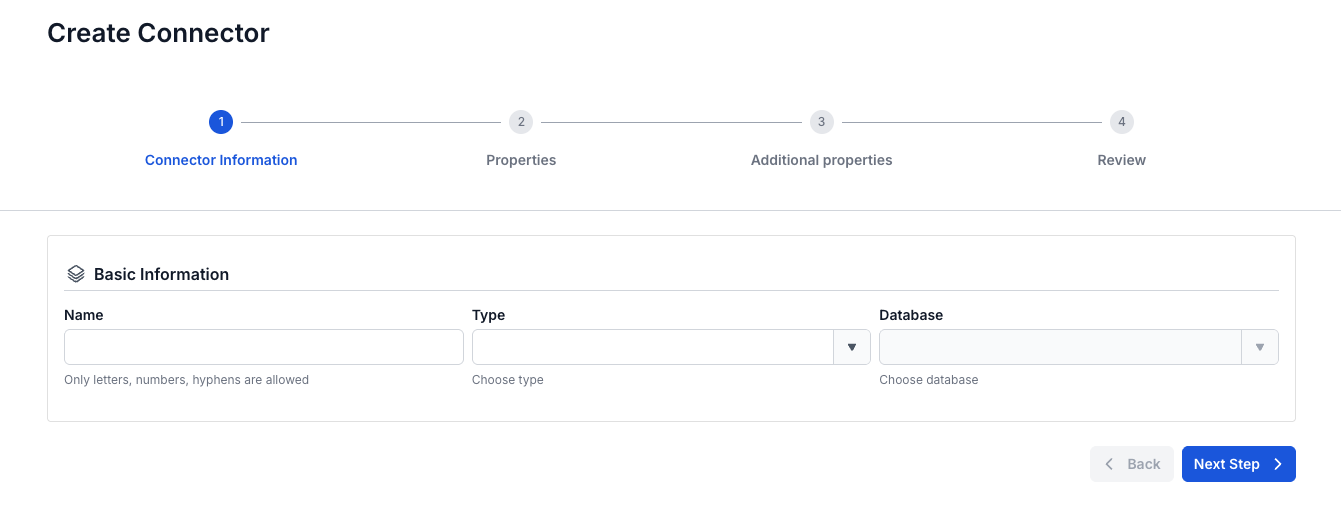
On the Connector Information screen, enter a Name, select sink in Type, and select Iceberg in Database.
-
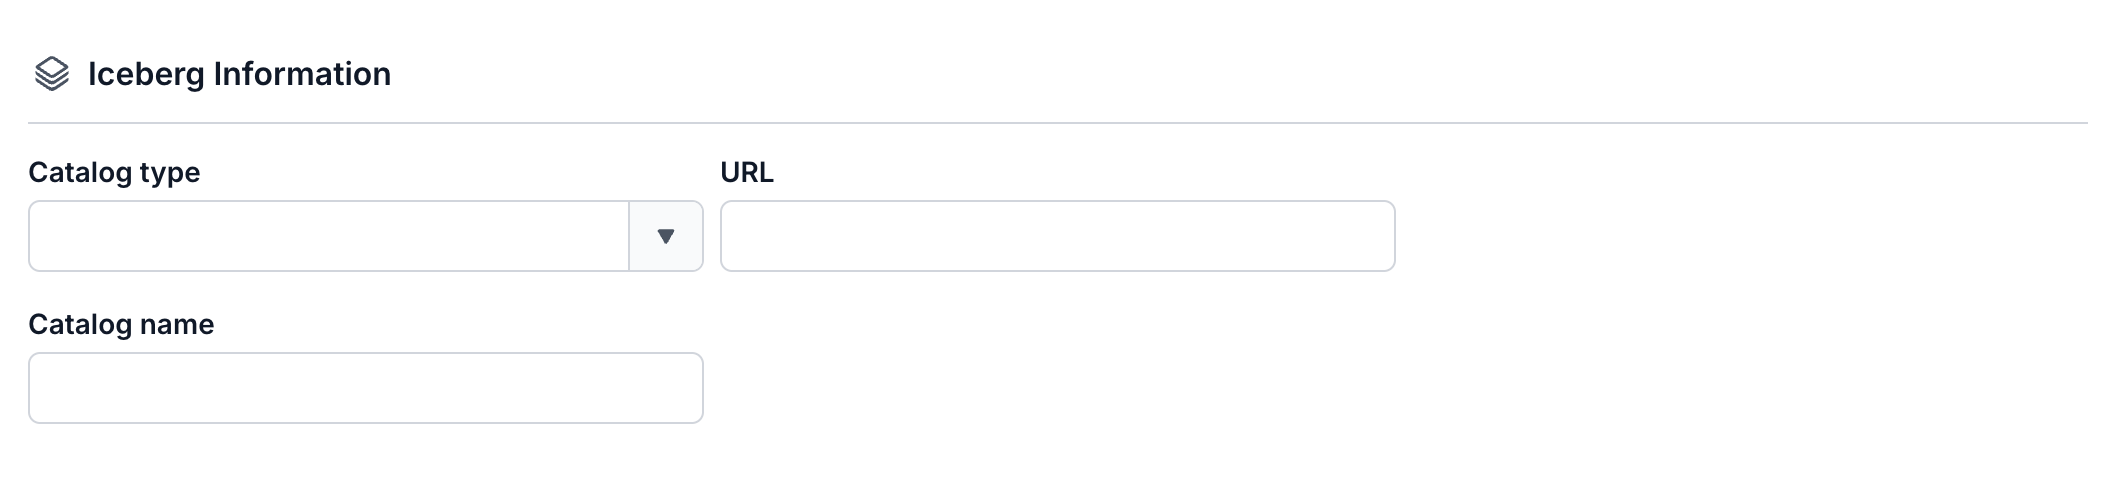
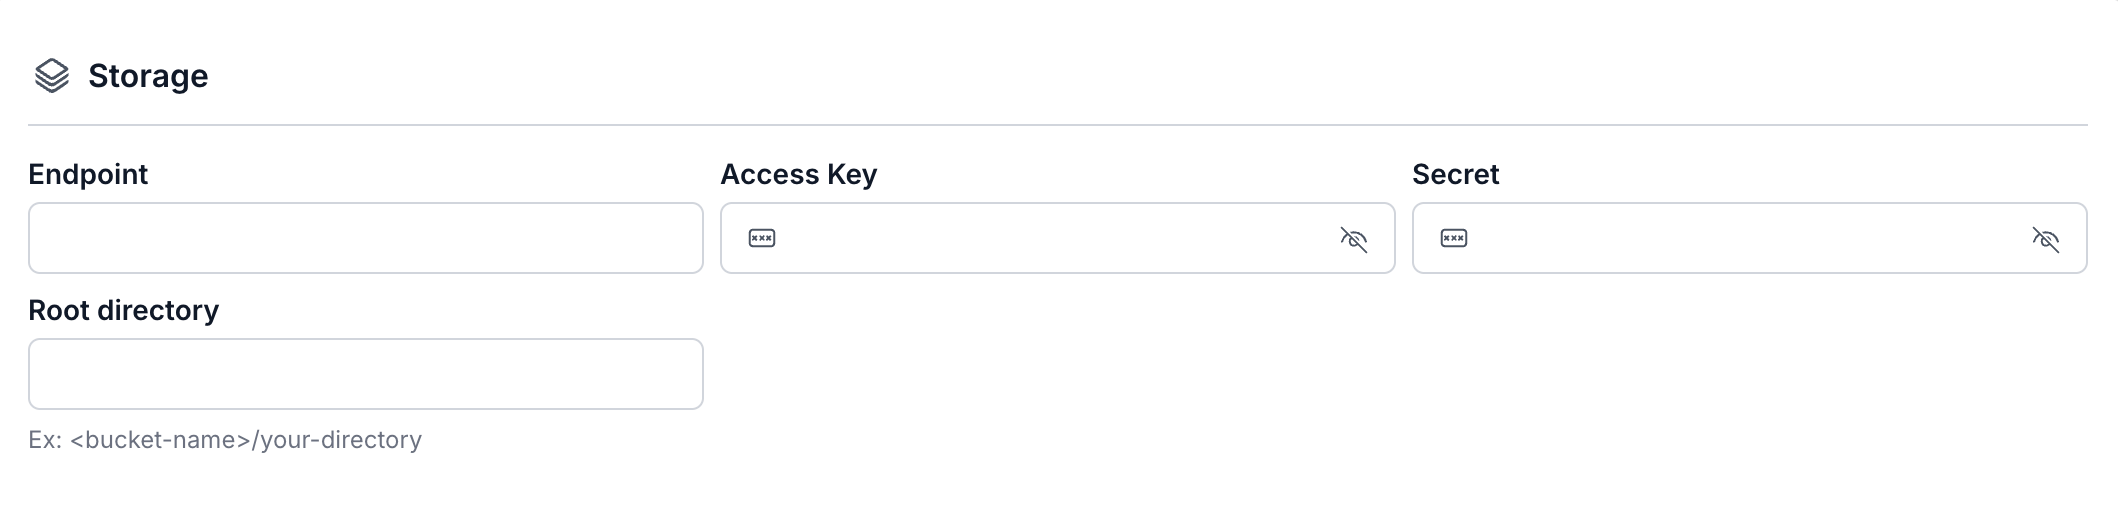
Select Next Step. On the Properties screen, enter the connection details, then select Test connection. Next Step becomes available after the test succeeds.
-
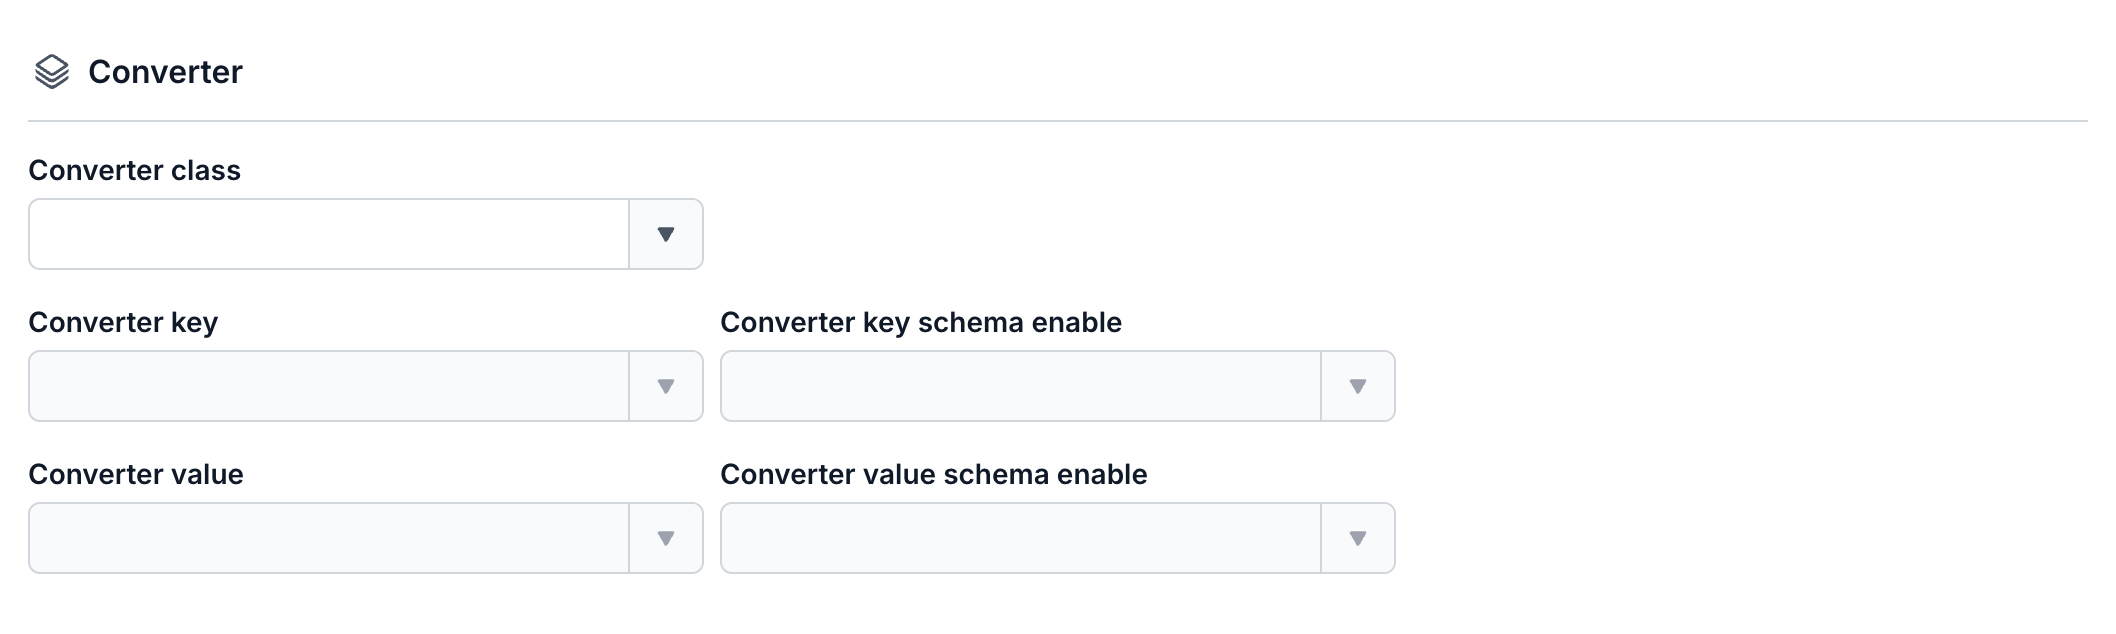
On the same screen, choose a Converter class and set the four converter fields, then select the topics to read in Topics.
-
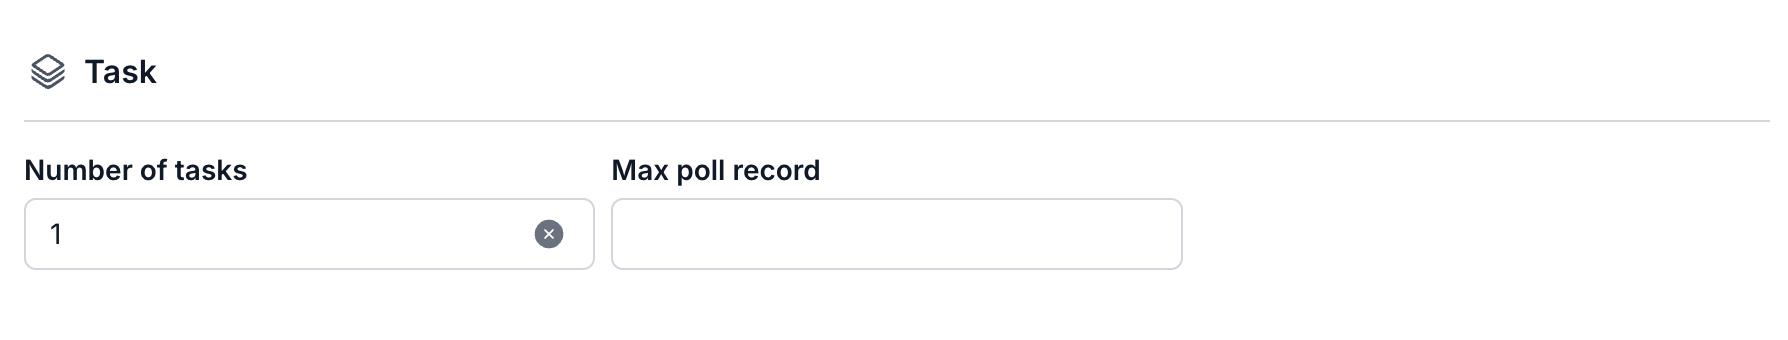
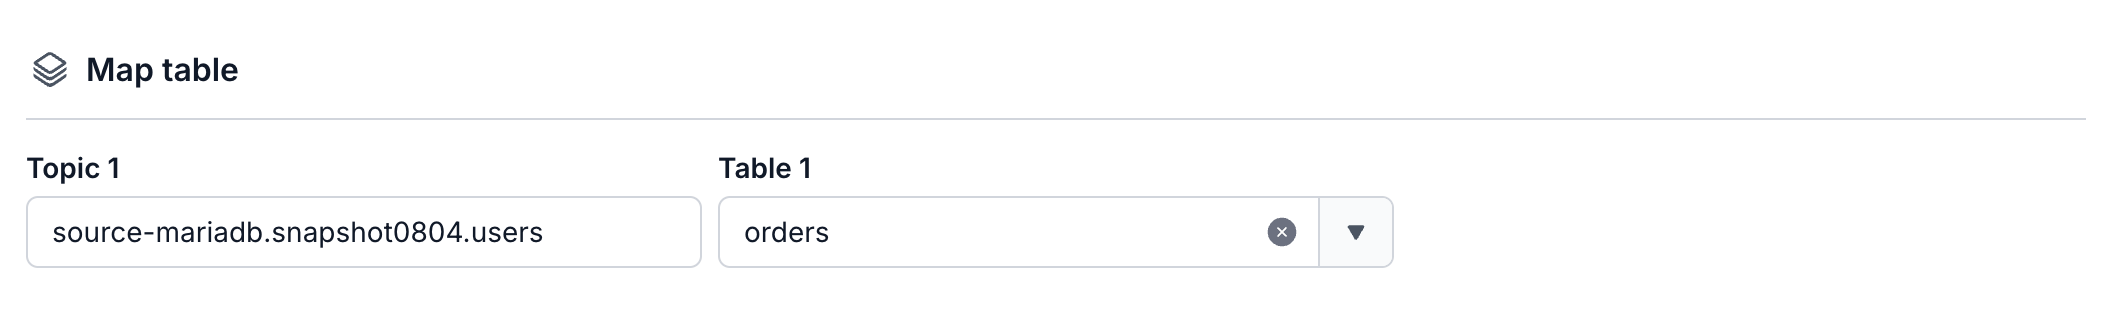
Select Next Step. On the Additional properties screen, set the fields in the Task, Source, Destination, Map table, and Error Tolerance sections.
-
Select Next Step and check the settings on the Review screen.
-
Select Create.
Connector settings
Connector information
| Field | Required | Description |
|---|---|---|
| Name | Yes | The connector name. Use lowercase letters, digits, and hyphens (-) only. Upper-case letters, _, ., and spaces are rejected with "Name has invalid characters". |
| Type | Yes | Select sink. |
| Database | Yes | Select Iceberg. |
Properties
This connector has no From FPT Database Engine option. Enter the catalog details in the Iceberg Information section and the storage details in the Storage section. See Connection mode for how Test connection works.
| Field | Required | Description |
|---|---|---|
| Catalog type | Yes | The type of the Iceberg catalog: Hive Metastore or Nessie. |
| URL | Yes | The URL of the Iceberg catalog. |
| Branch | Yes | Shown when Catalog type is Nessie, next to URL. The branch of the Nessie catalog. Select it from the list. |
| Catalog name | Yes | The name of the Iceberg catalog. |
| Endpoint | Yes | The endpoint of the S3 storage. |
| Access Key | Yes | The access key for the S3 storage. |
| Secret | Yes | The secret that goes with the access key. |
| Root directory | Yes | The root directory in the S3 storage, in the form BUCKET_NAME/YOUR_DIRECTORY. |
| Converter class | Yes | The converter class for this connector. The portal offers Iceberg replica. The four converter fields stay greyed out until you choose a class. See Converter. |
| Converter key, Converter key schema enable, Converter value, Converter value schema enable | Yes | How the connector reads the keys and values of the messages, and whether they carry a schema. With Iceberg replica, the key and value converters offer only org.apache.kafka.connect.json.JsonConverter, and the schema enable fields offer only true. |
| Topics (under Kafka topic) | Yes | The topics to read. Select them from the list, which shows the topics in the Kafka cluster of your CDC Service. See Topics. |
Additional properties
| Field | Required | Description |
|---|---|---|
| Number of tasks | Yes | The maximum number of tasks that run in parallel. Default 1. See Tasks max. |
| Max poll record | No | The maximum number of records the connector fetches in one poll. Default 2000. |
| Database Type | Yes | The type of the source database that the topics come from. With a source database selected, the connector applies updates and deletes by primary key. Without one, it appends every record. |
| File format | No | The format of the data files: parquet, avro, or orc. Default parquet. |
| Topic 1, Table 1 (under Map table) | Yes | The Iceberg table that receives the records of each topic. The connector creates the table if it does not exist. See Map table. |
| Mode (under Error Tolerance) | Yes | What the connector does with a message that it cannot read or convert. None stops the connector with status Failed. All skips the message and sends it to the topic you enter for failed records. The field has no default. See Error tolerance. |